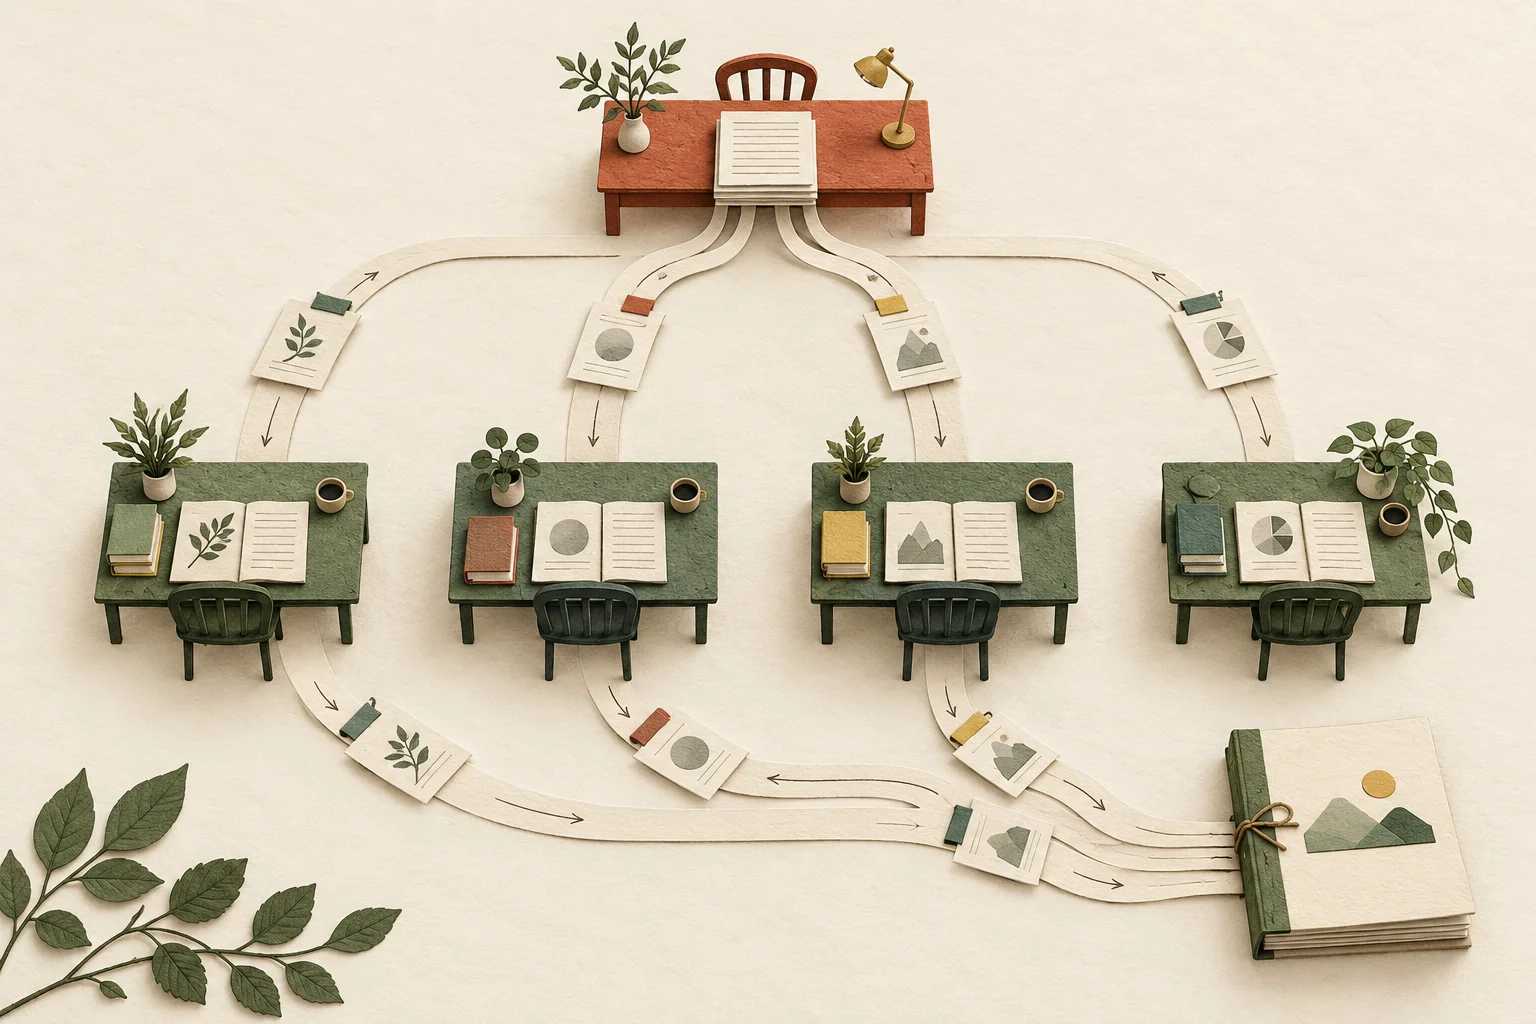
On 9 October, Claude Developers announced dynamic workflows for Claude Managed Agents in public beta. A lead agent plans work across other agents in stages and combines their findings. It is a concrete addition to the machinery around a model: the plan becomes something the server can execute.
The orchestration documentation describes an agent writing a program that coordinates other agents. The server runs it in the background. A request to review hundreds of documents is one example; the agent decides when the task warrants a workflow. Builders can guide that decision through the task description or system instructions.
That gives a useful shape to a reading job. Documents can be read in parallel, then passed to a later stage that reconciles the findings. The workflow reference also describes conditional steps, bounded revision, and handling an agent's failure. Those capabilities describe how work can be organised. They do not establish that a resulting answer is correct.
A completed run still needs checking
One detail in that reference deserves attention: a workflow can report completion even when work in a thread failed. The documentation directs clients to inspect the thread events to find those failures. A completed run is an execution status; it is not a certificate for every finding.
For a builder, my suggested first experiment is deliberately small. Give the system a few documents with answers you already know. Ask each reader to return the supporting passage and its location. Then ask a separate review stage to compare those findings with the originals. Include a document that cannot be read, and check whether the final answer makes that gap visible.
The experiment tests something more useful than how many agents can be launched: whether the combined report remains inspectable. An elegant summary that conceals a missing source has lost the advantage of dividing the work.
The orchestration guide recommends specifying when a workflow should be used and when a small task should be handled directly. It also warns that each participating agent consumes tokens. Start with a bounded task and judge the quality of the return before increasing the scale.